RECORDED EXPORT CHECK
Instagram transcript TXT export: punctuation and line breaks
Our TXT export preserved the tested Unicode punctuation and internal line breaks, but joined separate response segments with spaces.
These are offline checks of this site's formatting and export handlers with written text, not a test of an Instagram video's speech recognition.
What the files contained
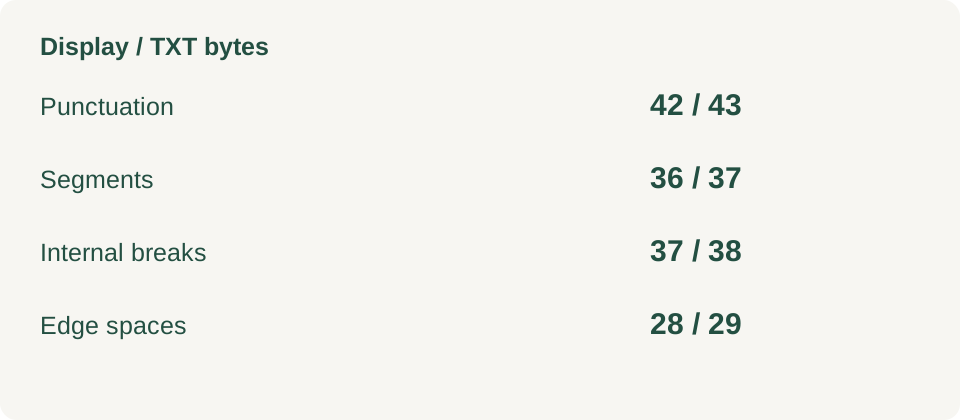
| Written fixture | Display bytes | TXT bytes | Internal LF |
|---|---|---|---|
| Punctuation + emoji | 42 | 43 | 0 |
| Separate segments | 36 | 37 | 0 |
| Internal line breaks | 37 | 38 | 3 |
| Edge whitespace | 28 | 29 | 0 |
What changed, case by case
In the punctuation fixture, our formatter produced a 42-byte UTF-8 display string, and the download handler produced 43 bytes while retaining its curly apostrophe, em dash, quotation marks and film emoji.
In the segment fixture, our three separate returned strings became a 36-byte display string joined by ordinary spaces; the downloaded file measured 37 bytes and had no internal line feed.
In the internal-break fixture, all three written line feeds remained in the display and clipboard sink, and the downloaded text contained those same three breaks plus its final line feed.
In the whitespace fixture, spaces at segment edges were removed while the double space inside the first segment survived; its displayed string measured 28 bytes and its download measured 29.
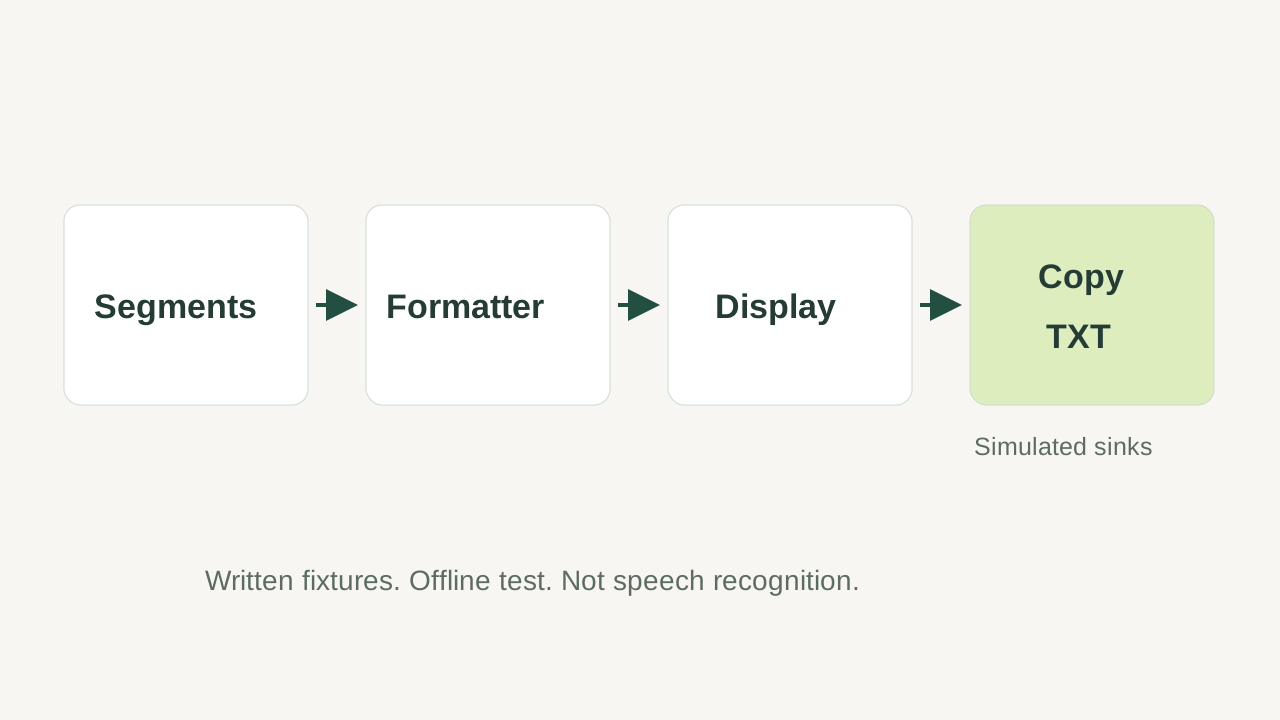
Across our four written fixtures, every clipboard-handler string matched the displayed string exactly, and every downloaded string matched that display followed by one final line feed.
Our punctuation fixture showed 7 words, both sentence fixtures showed 6, and the whitespace fixture showed 5; the retained internal spaces and line breaks did not create extra counted words.
Reproduce the check
On 6 November 2026, we executed the shipped segment formatter and frontend script in Node with in-memory page, clipboard and download receivers. The inputs were written fixtures. No video was submitted; no speech was recognized. The byte counts are UTF-8 file measurements.
Save the test script, formatter and frontend script together, then run node probe.mjs. Inspect the recorded input and output strings before rerunning.
Use the result without overreading it
If your downloaded text has fewer paragraphs, compare the displayed text first. A change at a response-segment boundary can come from formatting rather than a missing spoken sentence. To check a missing word, listen to that point in the original audio; this export experiment cannot settle it.
Did we test a real browser clipboard?
No. We checked the text passed to a simulated clipboard receiver. Operating-system clipboard behavior and mobile downloads were not measured by this experiment.
Does a matching TXT prove the transcript is complete?
No. Matching exports can repeat the same recognition error or omission. These fixtures begin after speech processing and contain no real video evidence.